
The failure pattern was too specific to ignore
I recently had to debug a receipt-printing problem in a cloud-based business system used on roughly 30 PCs across several branches in Lagos. The receipt itself was not simple: it had structured sale details, totals, branch information and a QR code that opened a verification page for the transaction.
On one thermal printer type, it printed exactly as expected. On two other printer types at the same office, the behaviour was completely different. One could produce an apparently endless stream of meaningless lines. Another printed garbled characters and malformed output. The same transaction, the same application and the same receipt could therefore move from correct to unusable simply by changing the printer connected to the workstation.
That pattern mattered. A general application bug should have failed generally. Instead, the failure followed the hardware implementation. It was also reproducible: changing transactions did not move the failure, while changing the printer did. That distinction stopped me from treating the bad output as random corruption and gave me a useful axis for every test that followed.
I kept looking at the wrong layer first
My first suspicion was the receipt. The QR code was an obvious candidate. Raster graphics can expose weaknesses that plain text never touches, so I considered image sizing, QR rendering, page width, fonts, CSS, encoding and the possibility that the receipt was simply too ambitious for some thermal devices.
I stripped the template down aggressively. I removed the richer presentation and tested a much more conservative output. That was useful diagnostically, but it did not solve the failing printers. The printer that already worked continued to work. The printers that failed continued to fail.
That result was more valuable than another template tweak. If a stripped-down receipt and the full receipt fail on the same hardware while another printer accepts both, then the layout is no longer the strongest explanation.
This is an easy trap in production debugging. The visible symptom was malformed paper, so every instinct pointed toward the visible receipt. But a receipt is the end of a chain: business data becomes markup or commands, those become a print job, the operating system and local application hand that job onward, and the printer interprets the bytes it receives. A defect at any one of those boundaries can appear as the same ugly piece of paper.

The control test that changed the diagnosis
The most important clue was that another retail application on the same Windows machines could print correctly to those printers.
That immediately narrowed the problem. The printers were capable of producing normal receipts. Windows could communicate with them. The hardware was not inherently broken. What differed was the route the print job took from the application to the printer.
I started treating the working application as a control rather than treating each failing printer as an isolated hardware problem. The question changed from “what is wrong with this receipt?” to “what does a broadly compatible retail printing path do differently?”
That control test also prevented a bad operational decision. Without it, the easy recommendation would have been to standardise on the one printer that happened to work and replace the rest. That would have hidden the software assumption by spending money on hardware. A compatibility layer should absorb reasonable variation in deployed equipment when the equipment itself is capable.
The real bug lived at the compatibility boundary
Thermal printers can look interchangeable from the outside while behaving differently at the protocol and emulation layers. A job that depends on one driver's interpretation of browser-generated output can work perfectly on one device and become unpredictable on another. Raw command printing has its own compatibility concerns too, but it gives the application much tighter control over what is actually sent.
The failure was therefore not simply “printer A works and printer B does not.” It was a compatibility mismatch between the application's printing transport and the way different thermal printer implementations interpreted the job.
That also explained why reducing the HTML did not cure it. I had simplified content while leaving the problematic communication path substantially unchanged.
Once I framed it that way, the design target became clearer. The application needed a conservative common denominator for thermal output, while still preserving the richer receipt as the authoritative presentation. The printer should receive an intentional thermal command stream, not an accidental side effect of whatever a browser, driver and device happened to agree on that day.
The fix was to separate the receipt from the transport
I restored the full graphical receipt instead of accepting the stripped-down version as the permanent solution. The receipt was not the thing that needed to become worse.
Then I separated the business representation of the receipt from the printer-specific transport. One shared receipt model supplies the sale header, line items, totals, payment information, verification details, footer and reprint state. From that model, the system can preserve the graphical receipt while also producing a conservative thermal-printer byte stream for the desktop printing bridge.
The thermal path uses deterministic character widths and wrapping, conservative text encoding, explicit separators and emphasis, controlled paper feeds and cut commands. The verification QR is generated as raster data rather than being left to a browser print engine to reinterpret. Printer selection is workstation-specific, and a print attempt waits for an explicit result from the local bridge instead of assuming that handing off a job means it printed.
The important architectural change was not a magic command. It was making the printer transport an explicit boundary instead of allowing receipt presentation and hardware communication to blur together.
I also kept the fallback path deliberate. If the local thermal bridge is unavailable, the application can still expose the graphical receipt rather than silently pretending that a native print succeeded. That distinction matters in branch operations: a failed print should be recoverable and visible, not converted into duplicate receipts because a user keeps clicking a button with no acknowledgement.
One cloud-side change, many workstations
The operational environment made the fix more interesting. The software is used across multiple branches, with around 30 PCs and a mixed population of thermal printers. Reconfiguring the receipt separately for every workstation would have been the wrong long-term answer.
Because the application is cloud-based, I could deploy the corrected receipt and printing contract centrally. The local desktop layer remains responsible for communicating with the selected printer, while the cloud application supplies a consistent receipt definition and print payload. That gives every branch the same receipt format without maintaining a different template for each printer model.
It also means future receipt changes have one authoritative source. The goal was not merely to make the three printers in front of me work. It was to remove the assumption that every thermal printer would behave exactly like the first one we tested.
The rollout was therefore a production change, not a laboratory demo. After the fix was deployed, the same receipt contract became available to the workstations already using the cloud application. That is the advantage of solving the problem at the correct shared layer: the organisation does not need thirty separate receipt forks just because its physical devices are not perfectly uniform.
Proof of the fix
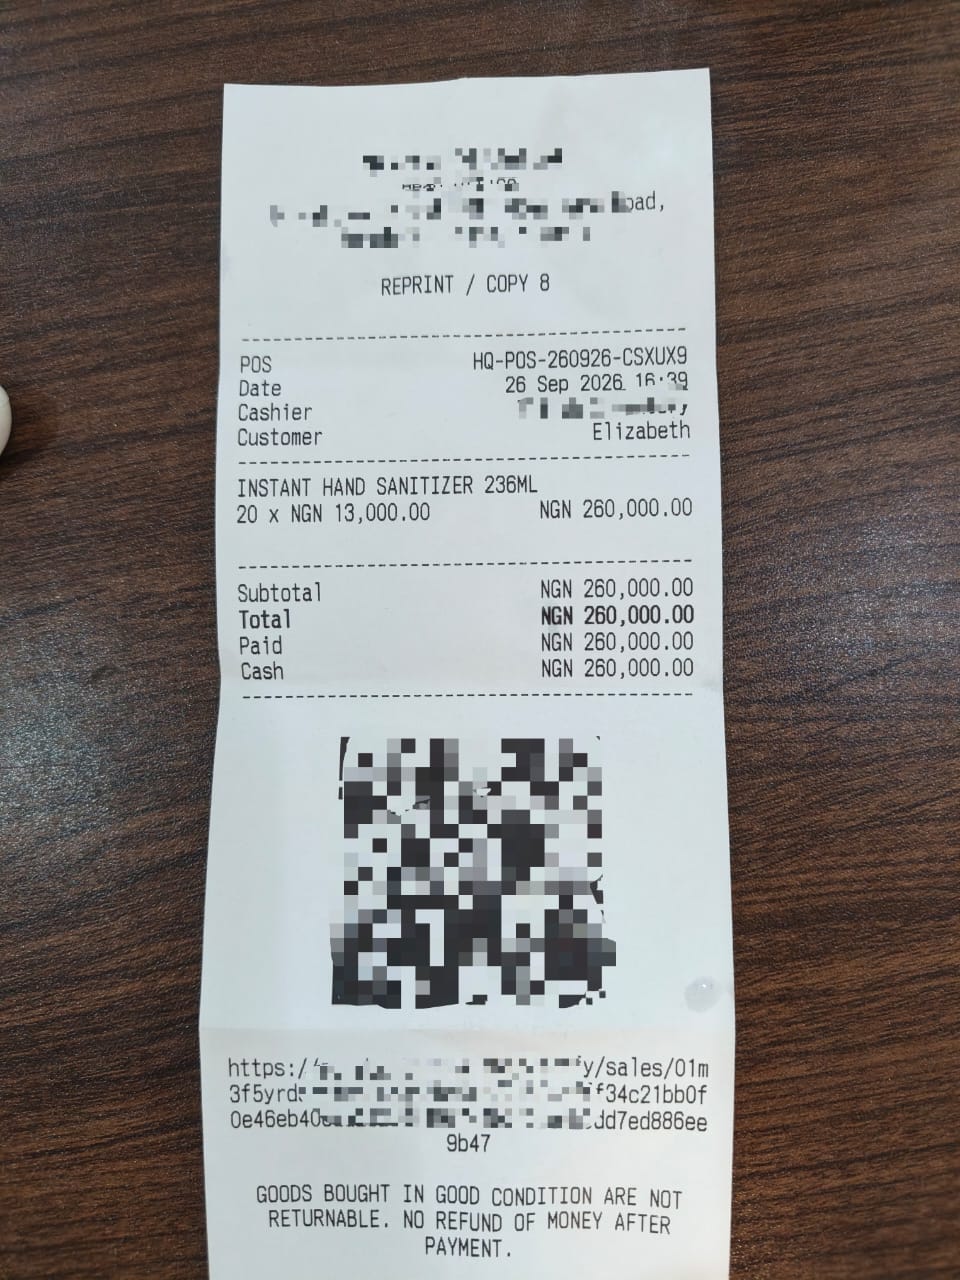
This is the finished receipt after the compatibility work. The same full format, including transaction verification by QR code, is now the standard output across the branches, workstations and supported thermal printers rather than a special template for one device.
The engineering lesson: debug the boundary, not just the component
The incident reinforced a debugging rule I keep finding useful in production systems: when two components work independently but fail together, spend more time investigating the boundary between them.
The application could render a receipt. The printers could print receipts. Windows could talk to the printers. Yet the complete path was still incompatible on some hardware. I lost time when I treated the visible output as proof that the visible layer was at fault.
The breakthrough came from changing the experiment. Strip the receipt down. Compare working and failing hardware. Find another application that succeeds on the same device. Keep eliminating layers until the failure follows one boundary. Then fix that boundary without unnecessarily degrading everything above it.
Hardware compatibility is rarely glamorous engineering, but in operational software it matters. A receipt that works beautifully in development and fails at a branch counter is still a failed feature. Production correctness includes the last metre between the application and the physical device.


